
NVIDIA NIM vs NeMo: the difference, then build with both
Eight hosted labs on real NIM endpoints, from a ReAct agent and a free RAG build to NeMo Guardrails.
Part of the AI Engineer Course.
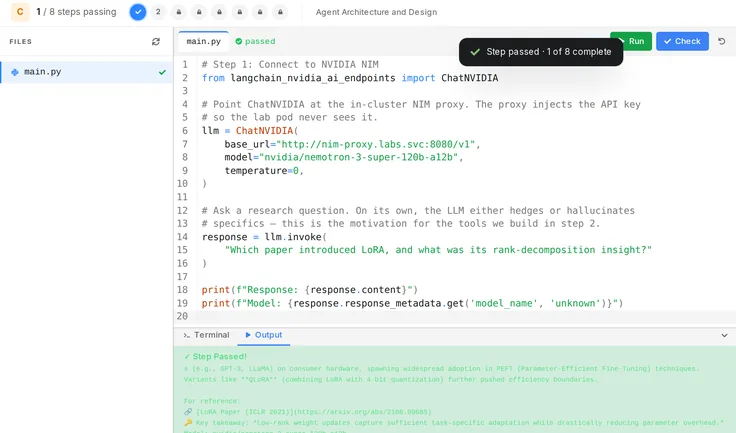
What you'll build
- A ReAct research agent on real NIM endpoints with LangChain, LangGraph and the NeMo Agent Toolkit
- A RAG pipeline on NIM: chunking, vector search, and an agent answering from your knowledge base
- A measured reliability gap between prompt-only JSON extraction and function calling, plus a two-tool chain
- A cheap-to-expensive NIM cascade with costs read from usage.cost, and an LLM-as-judge harness with accuracy and A/B scores
- Visual Q&A with two NVIDIA VLMs compared, image-query RAG with NeMo Retriever, and NeMo Guardrails jailbreak and topical rails on a support agent
About this path
NVIDIA NIM (Inference Microservices) packages a model behind an OpenAI-compatible API endpoint, so an agent, a RAG pipeline or a vision app calls it the same way whether the model runs in NVIDIA's cloud or on your own GPUs. NeMo is the family of tools around it: NeMo Retriever for embeddings and retrieval, NeMo Guardrails for input and output rails, NeMo Evaluator for scoring, and the NeMo Agent Toolkit for wiring agents together. Together they are the NVIDIA Platform Implementation domain of NCP-AAI and the NVIDIA platform tools line of the NCA-GENL Software Development domain, and the same services carry the RAG, evaluation, multimodal and safety work those exams test elsewhere in their blueprints.
The first lab is a ReAct research librarian on real NIM endpoints, built with LangChain, LangGraph and the NeMo Agent Toolkit, that searches a corpus of ML papers, reads abstracts and reasons over them to answer multi-step questions. Then RAG on NIM from document chunking to vector search to an agent answering from your knowledge base, and structured output, where you compare prompt-only JSON extraction against the function-calling API, chain two tools and measure the reliability gap. The operating stage cascades queries through cheap, mid and expensive NIM models, reads the real usage.cost field against an always-large baseline, then builds an LLM-as-judge eval harness with an accuracy metric and A/B comparison (the pattern NeMo Evaluator uses). Two multimodal labs follow: visual Q&A that sends images to a Vision-Language Model through the OpenAI-compatible chat endpoint, extracts structured fields from a receipt-style image and compares two VLMs, then image-query RAG that embeds a catalog with NeMo Retriever and grounds a VLM's answer in retrieved passages. The last lab guards an IT support agent with keyword checks, LLM-based validation and NeMo Guardrails jailbreak and topical rails.
All eight labs are hosted: they call NVIDIA NIM through the platform, need no GPU pod and no API key, run in the browser, and take 25 to 35 minutes each.
Who should join
- Python basics; you read and edit short scripts inside each step
- What a chat completion request is (a list of role-tagged messages sent to a model endpoint)
- No NIM, LangChain or NeMo experience; the first lab introduces the endpoints
Every step is checked against the live environment. Progress saves between sessions.
Outline
8 labs · about 4 hours
1. Build on NIM
A ReAct agent, then RAG on NIM (free) and reliable structured output with function calling.
2. Route and evaluate
Cascade across NIM model tiers and read the real cost, then score agent answers with an LLM judge.
3. Go multimodal
Send images to NVIDIA VLMs through the chat endpoint, then build image-query RAG with NeMo Retriever.
4. Guard it
Put NeMo Guardrails in front of an IT support agent: jailbreak rails, topical rails, LLM-based validation.
Run all 8 labs with Preporato Pro, plus every other lab and practice test.
$29.99 per month or $290 per year. Cancel any time.
Frequently asked questions
"Build a RAG Pipeline with NVIDIA NIM" is free with an account. The other seven labs are included in Preporato Pro ($29.99 per month or $290 per year), along with every practice test and every other lab on the platform.
They map most directly to NVIDIA's NCP-AAI: the NVIDIA Platform Implementation domain (NIM microservices, NeMo Retriever), plus Knowledge Integration for RAG, Evaluation and Tuning for the judge harness, multimodal development under Agent Development, and NeMo Guardrails under Safety, Ethics and Compliance. For NCA-GENL they cover the NVIDIA platform tools, LLM integration patterns and LangChain and LangGraph topics of the Software Development domain, and RAG fundamentals.
No. Every lab in this collection is hosted: the platform calls NVIDIA NIM for you, so there is no key to manage, no GPU pod to wait for and nothing to install. You work in the browser.
Just over four hours across eight labs of 25 to 35 minutes. Each step is checked automatically against the live environment: the cascade has to report its measured cost, the guardrail has to block the jailbreak, the eval harness has to produce its scores. There is no self-assessment.